
TokenLiquid
One key. 60+ frontier models. Three protocols.
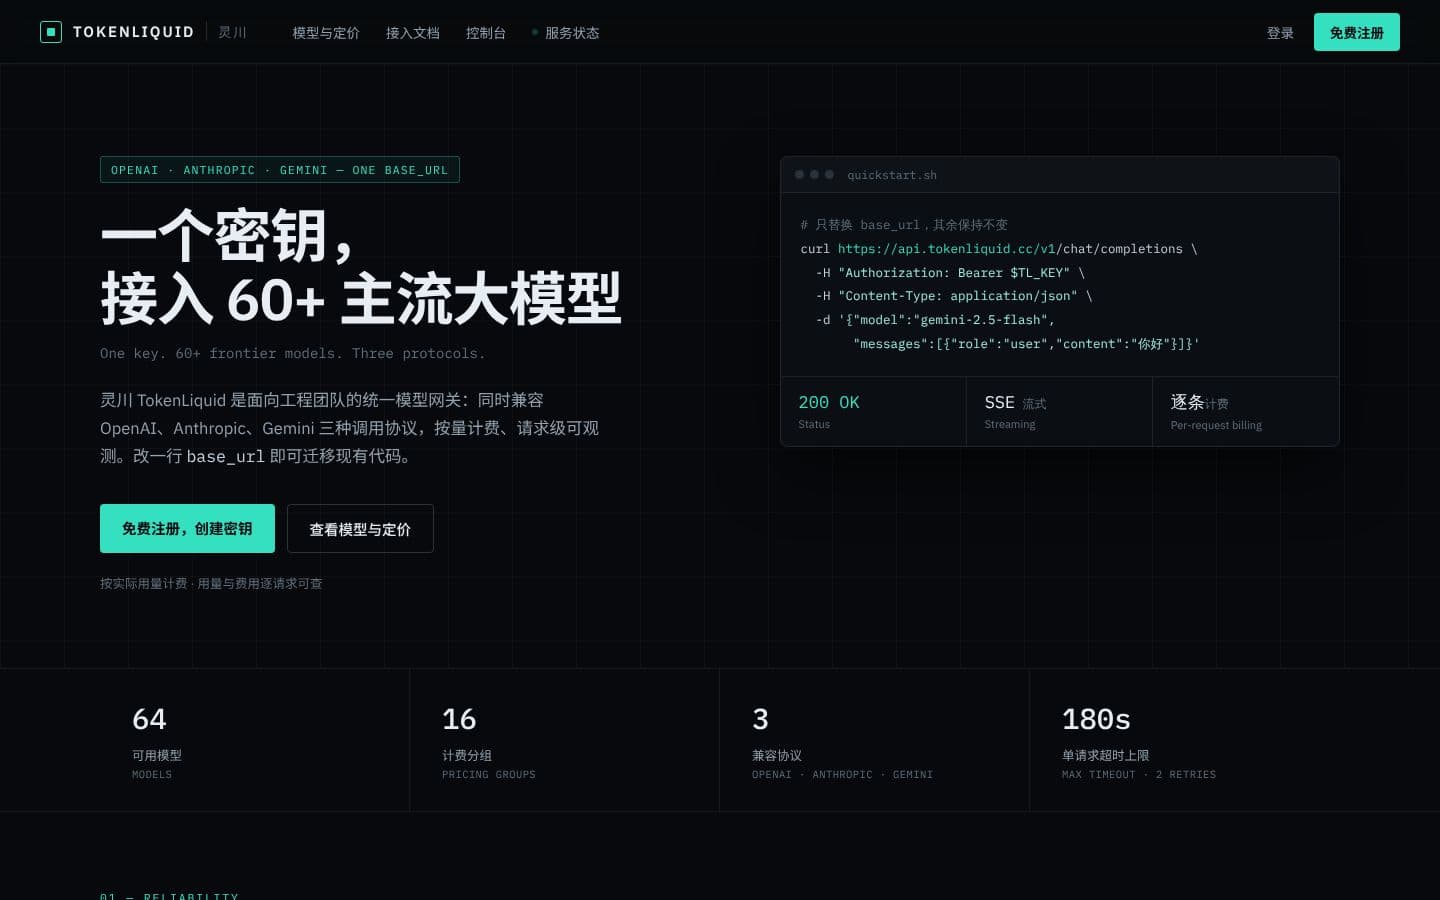
A unified LLM gateway for engineering teams. OpenAI, Anthropic and Gemini protocols behind one base_url, with pay-as-you-go billing, automatic failover and per-request observability.
> cat ./overview.md
TokenLiquid (灵川) is a unified model gateway: one API key reaches 64 models across providers, and it speaks the OpenAI Chat Completions, Anthropic Messages and Gemini native protocols at the same time. Migrating means changing one line — the base_url — and keeping your existing SDK.
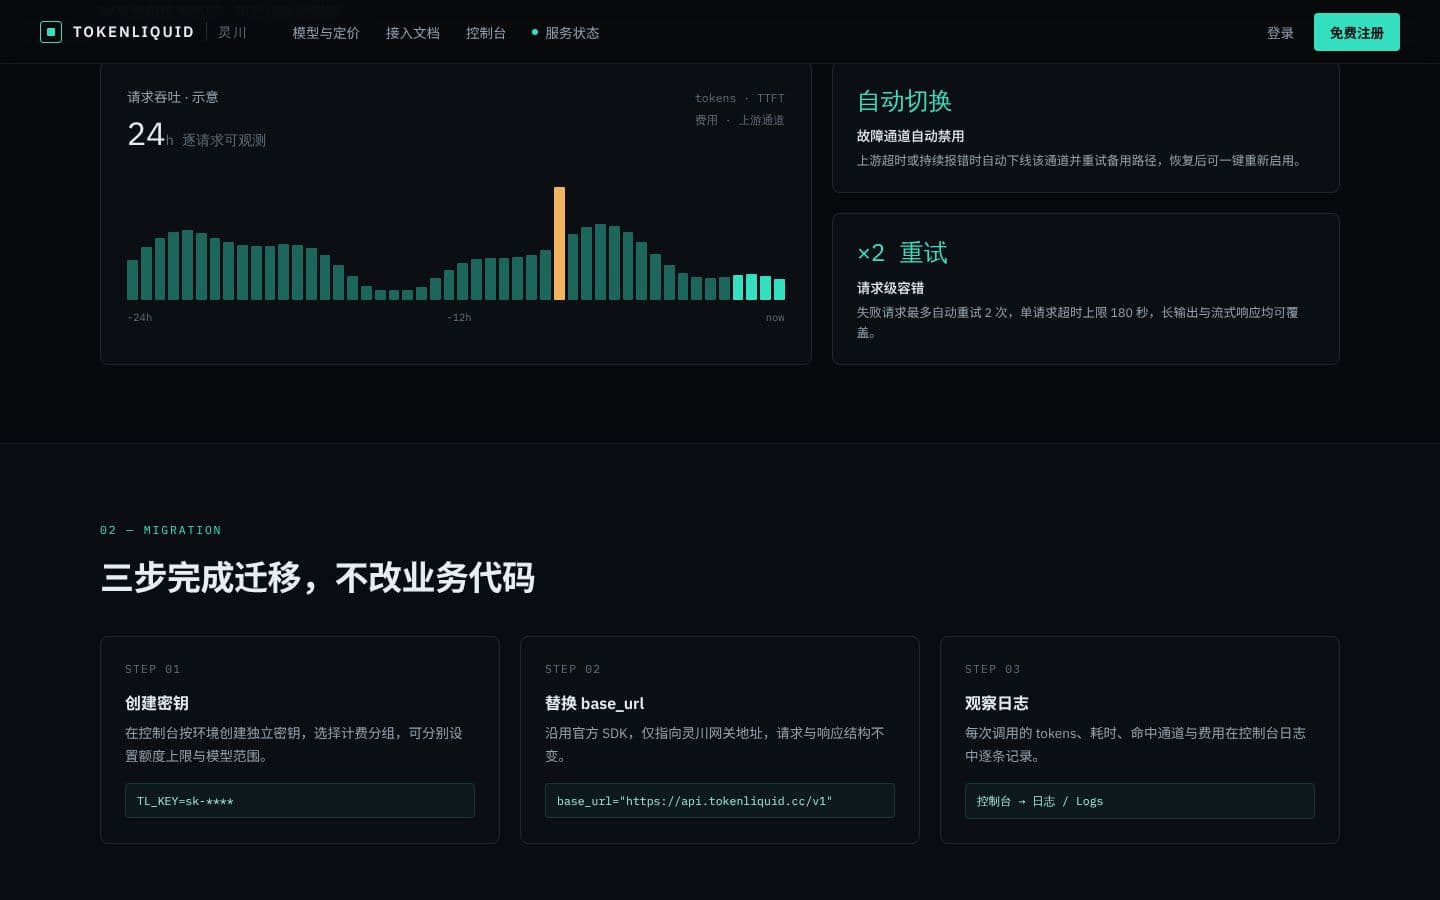
Reliability is built into the gateway. Failing upstream channels are disabled and traffic switches to a backup path automatically, failed requests are retried up to twice, and a single request can run for up to 180 seconds — long enough for streaming and deep-reasoning models.
Every call is recorded with its tokens, latency, routed channel and cost, so teams can trace spend request by request. Keys are scoped per environment with their own pricing group, model range and quota — and Claude Code connects directly via ANTHROPIC_BASE_URL.
> ls ./features
Three Protocols, One Endpoint
OpenAI, Anthropic and Gemini wire formats on the same key — the gateway handles protocol translation.
Change One Line
Point the official SDK at the gateway base_url; request and response shapes stay identical.
Automatic Failover
Unhealthy upstream channels go offline automatically and requests reroute, transparently to the caller.
Request-Level Observability
Tokens, latency, channel and cost logged per call, each traceable in the console by its request id.
Scoped Keys & Pricing Groups
16 pricing groups; each key locks its price, model range and spending cap. Failed requests are never billed.
Claude Code Ready
Set ANTHROPIC_BASE_URL and ANTHROPIC_AUTH_TOKEN and Claude Code runs through the gateway.
> open ./screenshots
> cat ./stack.json
{
"name": "TokenLiquid",
"category": "LLM Infrastructure / Gateway",
"stack": [
"OpenAI API",
"Anthropic Messages API",
"Gemini API",
"SSE Streaming",
"Usage Metering"
]
}
> grep -l "TokenLiquid" ./blog
One base_url, Three Protocols: Inside TokenLiquid
Why we built an LLM gateway that speaks OpenAI, Anthropic and Gemini at once, and what failover, retries and per-request logs look like from the caller’s side.
Nine Products, One Stack: The NGMOB Lineup
Haze Day, Hanakoi, TokenLiquid and Doubo join Floniks, Kolens, GoGlow, Naga and Hollow Lullaby. Here is what each one does, and where MCP, agents and orchestration fit in.